Category Archives: Security

The Influenced Influencer: Klippenstein Mistakes Russian Hands for Domestic Dissent

Ken Klippenstein reports that Task Force Raider, a CYBERCOM election security unit in San Antonio, has the American public as its real target.

His evidence for a missing foreign threat is the absence of a visible foreign hand. But that invokes a mistake we already have covered here as the Spanish police standard. Spain’s interior ministry announced it found no foreign amplification behind the Ceuta unrest. The European Commission then found Russian amplification from day one. Ken would be wise to read the European Commission tea leaves.

The Russian method puts the hand inside the target country, where it produces exactly the kind of mistake that Ken makes. Farmers, anarchists, ransomware crews and disposable recruits signing with a cover name coded wrong for their milieu carry the operation. Fragmented attribution is the Russia hypothesis. A reporter who reads scattered domestic voices as proof of a purely domestic story has described exactly the Russian warfare operation and then announced its absence.

Klippenstein’s own record settles whether foreign services reach American audiences. In September 2024 he published a document on JD Vance that Iranian intelligence had taken from the Trump campaign, and he said so in his subtitle. A hack-and-leak needs a publisher. He was the publisher. The column arguing that “influencing the influencers” answers a phantom threat comes from the influencer who was influenced.

His DCleaks example gives us the same. He describes the Obama administration taking DCleaks offline as a restriction of free speech. The 2018 GRU indictment identifies DCleaks as a persona and site created and run by officers of Russian military intelligence.

Removing a military intelligence front is counterintelligence. Calling it censorship hands the audience’s rights to the operator instead.

Klippenstein is not all wrong, so let’s give credit where it’s due. His documents describe three million messages sent to countries of interest, 56,000 PSYOP posts and a cellular blackout capability built in Afghanistan. The claim that the same tools now point inward rests on anonymous officers. We also know that Palantir has been aiming to do to America what its self-licking ISIS cream cone did to Iraq (generate domestic terror groups it wants money to destroy).

The precedent concern is sound and also more than a century old. Walter Nicolai’s service burned American factories in the First World War and got Wilson to investigate his own left. Vienna’s secret police built a card index of residents between 1849 and 1868 to track enemies of the state and ended with a file on everyone. Persona operations and a “best athlete” roster of cutouts are that index in cyberspace.

A foreign operation and a state using it as cover to police its own dissent are the sides of a single coin. Klippenstein reports only one side of it.

The foreign threat is documented on his own byline.

AI Warfare Targeting Black Authors: Wheatley to Kundizeza

The Academie Goncourt struck a novel from its longlist on 25 September, four days after an anonymous account with 92 followers declared it the work of a machine. The evidence was a single commercial detector. AFP ran the same passages through its own tool and got “very likely written by a human”, and seven other detectors disagreed with each other. The Goncourt cited plagiarism findings alongside the detector, but the plagiarism hunt began only because the anonymous account had made the author a target.

The author is Thelyson Orelien, 38, born in Gonaives, Haiti, resident in Montreal since 2010. His first novel, C’etait ca ou mourir, follows a teacher fleeing gang violence to Canada. It won the Prix du Roman Fnac on 21 September. The accusation from “Balance ton Claude” landed the same day. Within four days his Quebec publisher had suspended promotion, a book fair had withdrawn his guest of honour title, two newspapers had found copied passages in a short story and columns he wrote between 2012 and 2014, and the Goncourt had acted “to preserve the integrity of the Goncourt Prize” and its mission of honouring “literature written by women and men.”

On 24 September Le Figaro identified the account’s operator as one of its own columnists, Samuel Fitoussi, author of Woke Fiction. He had denied involvement to AFP all week while reposting the accusation from his named account. On 25 September he confirmed a “collective project” whose other members remain unnamed, and called the question of race conspiracist. The president of the Academie Goncourt, Philippe Claudel, had already told franceinfo why he thought the timing mattered: a Haitian, Canadian, Black, francophone foreigner, in a season when passions run high.

Fitoussi’s stated motive is fear that AI will end human writing. He is an associate member of Frst, a Paris fund that finances AI startups and began life as Otium Ventures under the Catholic billionaire Pierre-Edouard Sterin. The detector he relied on, Pangram, raised $9 million in July in a round led by Menlo Ventures. Menlo’s partner wrote that the firm led the round as part of the Anthology Fund, the vehicle it runs with Anthropic, whose assistant gave the account its name. Pangram describes its detector as a model trained on tens of millions of documents known to be written by humans.

The Goncourt was the second prize of the year to act on that detector. On 14 May the Commonwealth Foundation named five regional winners of its short story prize. A Wharton professor ran the Caribbean winner through Pangram, “The Serpent in the Grove” by Jamir Nazir of Trinidad, and posted the result: 100 percent AI. Granta, which published the winners, asked Claude whether the story was machine written and put the answer in a statement. Its publisher Sigrid Rausing wrote that the judges may have awarded a prize to AI plagiarism and that Granta might never know. On 19 June Granta ended its external publishing partnerships. On 22 June the Foundation cleared all five winners. It had refused to run detectors on unpublished work and instead asked every winner for working drafts, time-stamped documents and notes. Nazir was named overall winner on 30 June. Vauhini Vara of The Atlantic then fed fifteen years of winning stories into Pangram and found that the only ones it flagged were three of the five from 2026.

On 6 October the Caine Prize for African Writing gave its £10,000 award to “The Blue Fighter” by Simbarashe Steyn Kundizeza of Harare, chosen from 407 entries across 27 countries. On 11 October Vara published her Pangram scan of the story under the headline “Yet Another Literary Prizewinner Seems to Be AI”. The detector flagged almost the whole text. It had passed every earlier Caine winner she tested and “The Whistleblower”, a thriller Kundizeza published in 2021. His agency told her it has full confidence the work is his. The same day the Caine Prize Foundation opened a review. Vara noted in the article that detectors flag the tidy English of writers for whom it is a second language. Stanford measured this in 2023: seven detectors were near perfect on essays by American eighth graders and flagged 61 percent of essays by non-native speakers as machine written.

The accused writers in May, September and October came from Trinidad, Haiti and Zimbabwe. The detector was the same each time.

Zimbabwe has seen this office before. In 1954 the Southern Rhodesia government set up the African Literature Bureau. Its stated purpose was to grow a reading market in Shona and Ndebele. Its working purpose was to screen every manuscript by an African before a publisher could print it, and to keep politics out. Solomon Mutswairo’s Feso, among the first novels by an African, came out under the Bureau in 1956, and the Ministry of Education later struck it from the reading list for African schools. Philemon Mutambara, a teacher with a Fort Hare degree, submitted a Shona novel in the 1960s. The Bureau returned it with demands for changes and a reader’s report telling him that the books it had already published “would be an invaluable guide to you as the sort of standard required for publication.” He refused, died in 1968, and the novel appeared 51 years after he wrote it. A white office in Salisbury held a model of what an African story should read like and graded manuscripts against it. Flora Veit-Wild, who wrote the social history of that system in Teachers, Preachers, Non-Believers (1992), later interviewed the Bureau’s post-independence director, who told her there had been no censorship, only screening. Pangram holds a model of what a human story should read like and grades manuscripts against it. It flagged a Harare writer’s prize story and passed the one he wrote in 2021.

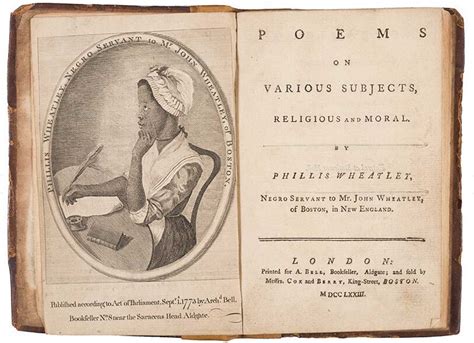
Black authors in the French and English worlds have been asked to prove they wrote their own books for 250 years. Phillis Wheatley was examined by eighteen Boston men in 1772, Governor Thomas Hutchinson among them, before a London publisher would print her poems, and their signed certificate opens the 1773 edition.

Bakary Diallo, a Senegalese rifleman, published Force-Bonte in Paris in 1926 and was assumed for decades to have had it written by his French patrons. Camara Laye’s Le Regard du roi (1954) was attributed in 2002 by the scholar Adele King to two Belgians in Paris, his landlord and a reader at his publisher. Yambo Ouologuem won the Renaudot in 1968 for Le Devoir de violence, faced plagiarism charges from 1971, and published nothing after 1972.

A white author gets the opposite treatment. Michel Houellebecq copied Wikipedia passages into La Carte et le Territoire, admitted it, called it collage, and won the 2010 Goncourt anyway.

Nazir handed over his drafts and timestamps to keep his prize. Orelien is compiling a dossier with his editor to prove he wrote his own book. Kundizeza’s agency is vouching for him while a foundation reviews his story. Wheatley stood before eighteen examiners in Boston over 250 years ago.

The information warfare against Black authors hasn’t changed much.

Micah Lee’s Tinfoil AI Privacy Post Skips the Privacy

Micah Lee’s new post tells readers NOT to use OpenAI or Anthropic, and points them to Tinfoil with the advice to:

read their docs on secure enclaves and remote attestation.

Fine advice. But the details matter, and he gets them dangerously wrong in a post about being private.

His post argues for open weight models on Tinfoil’s secure enclaves for anything private. He calls Tinfoil “the company that’s doing the most work here” and offers no comparison to back it. And he runs Tinfoil through OpenCode, a coding harness that talks to any OpenAI-compatible endpoint.

Tinfoil’s page for coding agents lists OpenCode by name and says plainly:

OpenAI-compatible clients don’t perform connection-time attestation themselves.

No attestation at connection time. That’s a big problem for someone recommending Tinfoil as the company doing the most work. Attestation is the check that the enclave is real hardware running the code it claims to run. Tinfoil’s answer is a local proxy that runs that check before each request leaves the machine. Without the proxy, what remains is an audit log reviewed after the fact, which the Tinfoil SDK documentation calls “a much weaker guarantee.”

Much weaker. The work Tinfoil does goes unused in the setup he describes.

Later in the same post he waves off OpenCode Go’s privacy terms:

Of course, it’s just a promise. Nothing technical guarantees it.

An enclave left unchecked at connection time is also a promise. The premium that he pays to Tinfoil is for hardware that can prove itself, yet that proof counts only when the client asks for it. His post never mentions the proxy. So what is he paying them for exactly?

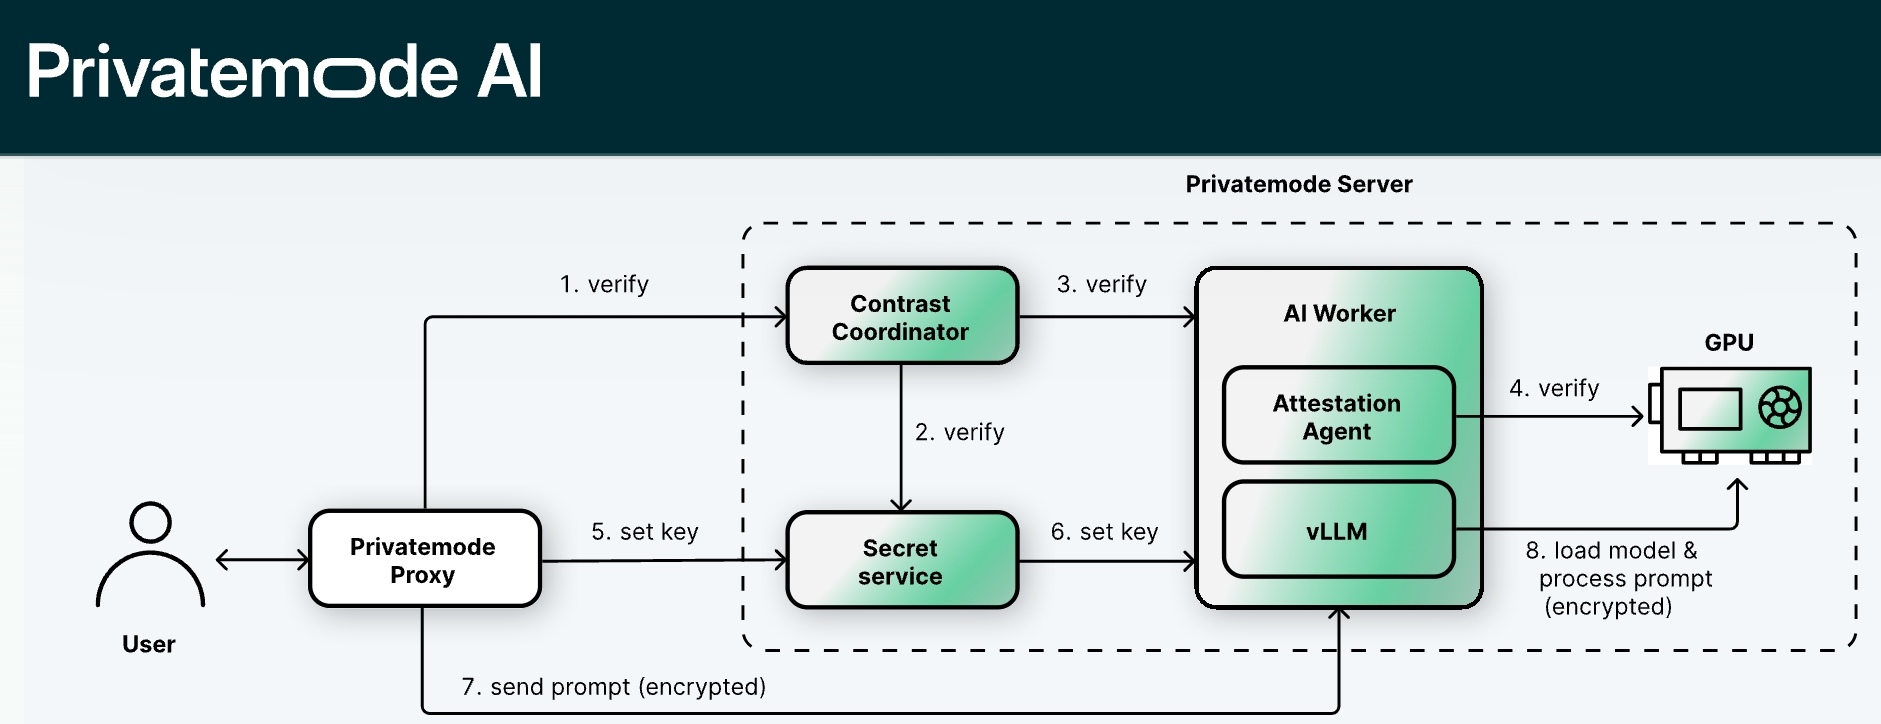
Privatemode, from the German company Edgeless Systems, puts that check in its standard client. A small local proxy handles encryption and attestation, and verification runs on the user’s side before any data goes out.

Notably Micah trusts Mistral with your data for being French. The same reasoning favors a German service where verification is the default path. Tinfoil is American.

The larger problem is actually on his laptop. He warns readers away from ZCode, Z.ai’s coding harness, because it was caught uploading local source code without consent. That is what any harness can do with the access it gets: read a file and send it somewhere. His replacement is OpenCode, a different harness with the same reach into the same machine, and he recommends that setup for malware analysis and pen tests.

Why? No thanks!

The enclave security only protects the model while it computes. The agent’s file reads and shell commands happen outside the enclave, on his laptop and across the open internet. The private part of his private AI is the inference. See the disconnect?

The same gap shows up in how he splits his work. He sends “completely public work” to OpenCode Go because the code is already open source. A coding agent sends whatever it reads into the conversation, command output included, and the conversation goes to the router and the provider behind it. The repository is public. The session holds whatever the agent read from his machine.

On the models themselves, he writes that it’s “perfectly fine, safe, and secure to use these open weight models,” as long as readers keep their chats away from the companies that made them. The weights are the company’s work. Open weights let anyone run a model, and they reveal very little about what it was trained to do. Researchers at Anthropic showed in 2024 that a model can be trained to act normally until a trigger appears, and that standard safety training left the hidden behavior in place. Trusting the weights while distrusting the lab is still trust in the lab.

He is right that the frontier labs gate access to their strongest cyber capability, and he understates how far it goes. Anthropic’s least restricted tier is vetted in collaboration with the US government, and every organization in its verification program accepts data retention so Anthropic can monitor for misuse. Security researchers pay for fewer refusals from the vendor by sacrificing privacy, if you can believe that.

His answer is a model without “a cop watching over your shoulder.” A filter at the provider serves the provider’s policy. Removing it leaves the operator with zero controls of his own while the agent runs malware analysis on his machine. That’s not logical. The control that protects the operator sits outside the model, in his hands, so it can decide what each proposed action may touch. Refusals trained into a model can be removed. But a gate setup outside the model stays in place when the model changes.

He also says the labs can share your data “or do whatever they want.” Anthropic’s commercial terms bar training on customer content, and its government request policy requires valid legal process outside emergencies. Those are promises, the same class he assigns to OpenCode Go and files under inference without privacy. Tinfoil without connection-time attestation belongs in that class too, yet he files it under private. A promise becomes a guarantee through verified attestation, which is the step missing from the Tinfoil setup he describes.

I built Wirken for what his post is trying to say. It is a model-agnostic gateway between the model and everything the agent can touch. Every tool call passes a gate that allows it, asks a human, or refuses it. Outbound traffic reaches only allowed hosts, and each action goes into a signed audit log that verifies offline. The same gate runs whether the model is open weight on my own GPUs, Tinfoil, Privatemode or Claude at Anthropic.

Changing the model changes who proposes the action. The proper gate decides whether it happens. And a proper TEE has attestation as default behavior.

Anthropic’s Worm Paper Shows Why Nobody Needs Anthropic

Anthropic’s Frontier Red Team gave Qwen3.5-9B access to Opus 4.8 as an advisor and measured whether the advice made the small model better at setting up inference on unfamiliar hardware. Success rates stayed flat. The team offered the advisor as a tool call and, in a second arm, pushed its advice to the small model whenever it stalled. Both arms stayed flat.

A version first trained with reinforcement learning to call an advisor on coding problems still struggled to ask for useful help. The authors take that result, add that small models are persistent agents on their own, and judge coordination more likely to come from:

a large model handling high-level strategy and spinning up small models as subagents.

Ok, supervised agent swarms is one way of working, but that doesn’t mean it is a necessary one.

The same paper builds its threat model on the independence of small models. A small replicator carries its own weights onto cheap devices, and the authors judge it hard to shut down because the swarm has no central point to switch off.

A swarm is a distributed compute model, and distributed systems carry their own power-off by design. Every node runs the same program, and the program checks a condition before it continues: a lease that expires, a signed stop command from any peer, a heartbeat that goes quiet. Any one of those switches off the whole swarm with no central server anywhere. The Internet already works this way. A BGP route withdrawal propagates router to router with no central router. A TLS certificate stops working on the expiry date written into it at issuance. A DNS record dies on its TTL.

The paper’s own precedent shows the same property. FritzFrog takes commands from any peer, which is how Guardicore joined the network with its own client and issued commands to it.

A distributed swarm has no central point and an off switch at the same time.

The design question is who holds a key, and the paper very suspiciously never asks it, perhaps because they don’t fully understand the topic of swarm safety. I have written about it extensively in designing a swarm harness called Wirken, which is open source and free, for those who want more details.

The hardware work seems logical. The team ran Gemma4-26B-A4B across 15 off-brand TV boxes at 0.39 tokens per second, on ARM processors limited by memory bandwidth.

The problem is with the inference made by the authors from those experiments.

A Large-model advice leaves small-model success flat, asked or unasked.
B Small replicators are hard to kill because the swarm has no central point.
C Expect a large model to direct small subagents.
Paper A ∴ C, while holding B

C needs a channel from the large model to the small one that carries useful instruction. A measured that channel and found it flat. The arm that pushed advice whenever the small model stalled is the closest the paper comes to testing a large model intervening in a small model’s work, and it showed no significant gain. A counts against C.

The paper derives C from A in a single sentence, so the authors reach their conclusion from evidence against it.

The paper has a point. It reports that small models complete individual replication steps and make errors when chaining them end to end, so a large model handling the chaining while small models handle the steps is a coherent design.

The paper offers that design as an expectation. And then the expectation is left untested, therefore unproven. Or perhaps they tested it and decided not to publish the result because it made Anthropic look even worse than this paper already does.

C also cancels B.
B depends on the swarm having no central point.
C adds a central point.

A large model directing many small ones is a central point by construction, and it runs where large models run, in a datacenter or behind an inference API. The paper describes an API-based replicator as one that needs a model provider to serve it unknowingly, and judges it easier to discover. A strategist on an API puts command of the worm inside a vendor’s product, where the vendor holds the logs and can revoke the keys. Taking out the strategist takes out the coordination C describes. B and C each describe a replicator, and they describe two different ones.

Takedown logic tends to aim at central command. In April 1970 Nixon told the nation that American and South Vietnamese units would attack the headquarters for the entire Communist military operation in South Vietnam. The Pentagon’s own Vietnam War commemoration records that the incursion never found the headquarters it had hallucinated. This is what should come to mind when reading Anthropic claims.

Microsoft disabled Rustock in 2011 by seizing its command and control servers from five hosting providers in seven US cities and severing the IP addresses that controlled the botnet. FritzFrog and P2PInfect put command in the peers instead. Guardicore found that FritzFrog distributes control across all of its nodes, and Unit 42 found P2PInfect running on a peer-to-peer command and control network. The Anthropic paper cites both as the precedents for its small replicator. But the paper’s own data points us to a very different conclusion.

In its Memento harness, each Qwen3.5-9B instance kept notes on what it tried and what failed, and a fresh instance inherited them. Setup success rose from 45 percent in the first generation to between 61 and 84 percent in later ones. Small-to-small transfer raised success, while large-to-small transfer left it flat. The one Anthropic model in the experiments, Opus 4.8, appears only as that advisor.

D Small models improve on notes inherited from small models.
Supported A ∧ D ∴ small coordinates with small
Non sequitur A ⊬ C
Inconsistent C → ¬B

The supported inference keeps the premise of B intact: the swarm has no central point. It describes the replicator the experiments produced: small models running their own weights and passing notes forward to their successors.

Therefore, the paper’s sentence that a large model is the more likely director follows from nothing in its data.

It appears to be a hallucination by the authors.

In April I read the Mythos system card and found an engineering research voice that refused to sign the number that the marketing voice was pushing in the headlines. The research voice said the model weaponized two bugs another earlier model found, in patched software, with the sandbox off. The marketing voice said thousands of zero-days. I think we all know how the marketing turned out.

Six months on, I see the conflict of these two voices again, compressed into a single paragraph. Engineering says that a large model adds nothing to a small one. Marketing, in the next sentence, puts the large model in charge. A company with a mature risk owner would have reconciled the giant gap between those two sentences before publication. It strikes me that Anthropic doesn’t have strong enough security leadership.

Every measured result in the paper has small models working alone and teaching each other. That makes sense. That’s logical as well as consistent with Internet history. Nobody needs an IBM. Nobody needs Amazon. The market should not favor hedge and capture by artificial pressure. The paper’s own data shows a large model adds nothing to a swarm of small ones.

Nobody needs Anthropic.